How to Deploy vLLM NVIDIA Dynamo Inference for High-Throughput Serving
 Technology
What to know
- Learn how to deploy vLLM NVIDIA Dynamo inference in production with Docker Compose and tuned PagedAttention to eliminate memory fragmentation. How to Deploy vLLM NVIDIA Dynamo Inference for High-Throughput Serving on SitePoint.S1
- NVIDIA Dynamo is an open-source, high-throughput, low-latency inference framework for deploying large-scale generative AI and reasoning models across multi-node, multi-GPU environments. It boosts LLM inference efficiency and reduces time-to-first-token (TTFT)...S2
Timeline · newest first
1mo
Sitepoint
How to Deploy vLLM NVIDIA Dynamo Inference for High-Throughput Serving
Learn how to deploy vLLM NVIDIA Dynamo inference in production with Docker Compose and tuned PagedAttention to eliminate memory fragmentation. How to Deploy vLLM NVIDIA Dynamo Infe…
1mo
Dev
Deploying Inference Using NVIDIA Dynamo and vLLM
NVIDIA Dynamo is an open-source, high-throughput, low-latency inference framework for deploying large-scale generative AI and reasoning models across multi-node, multi-GPU environm…
Related stories
 Technology
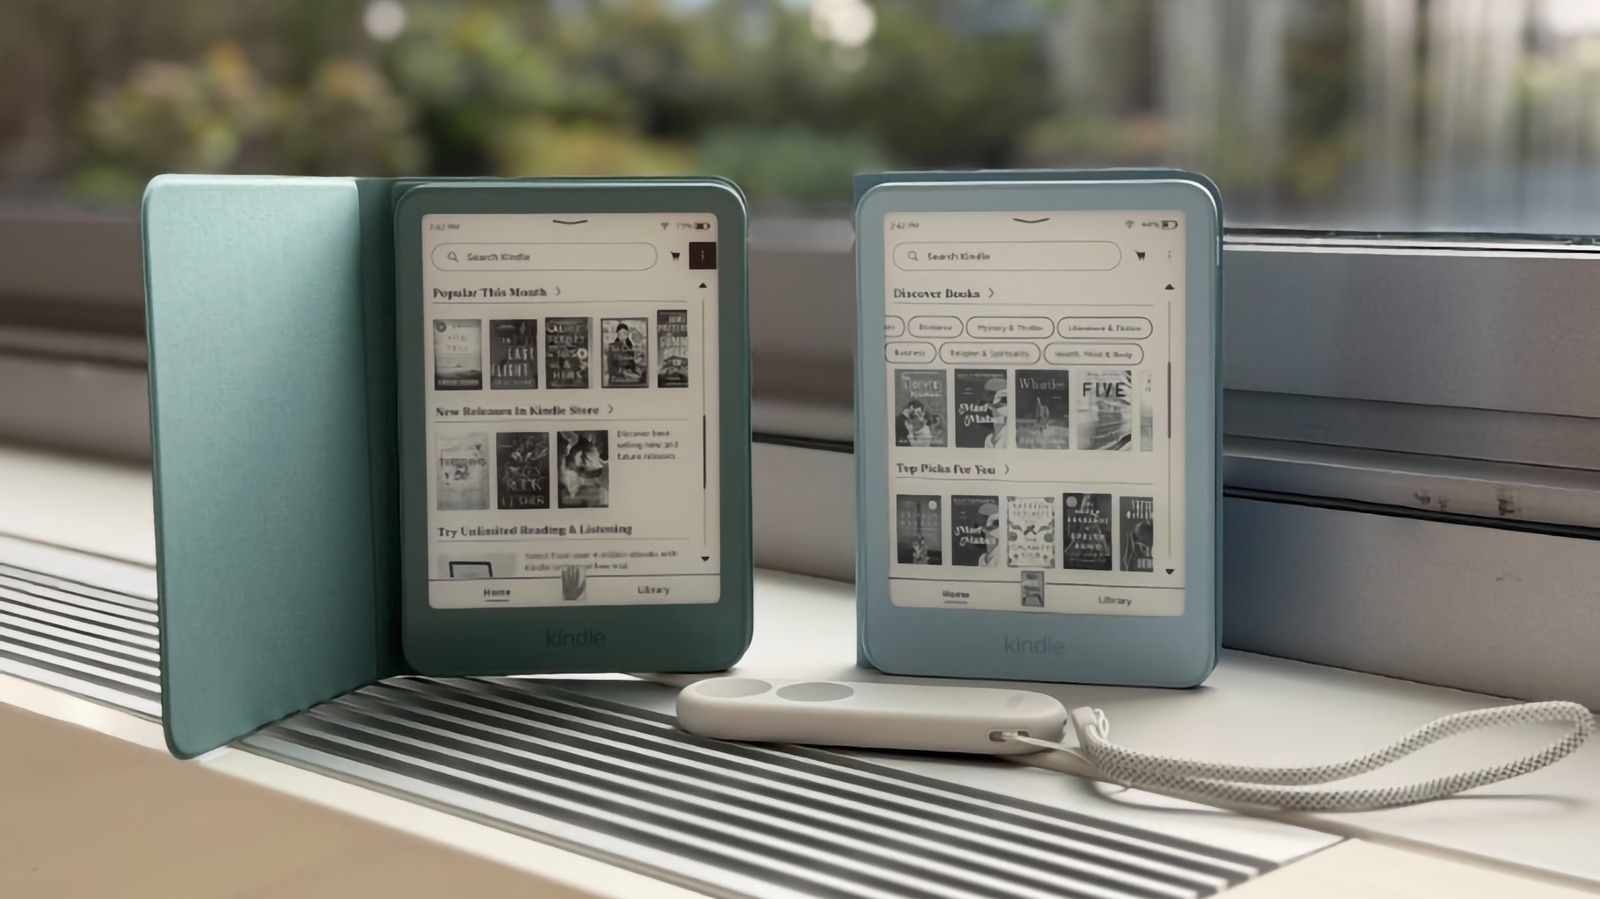
Amazon Renames Kindle Unlimited to Kindle Plus, Expands Audiobook Selection
2 outlets
1w
 United States
 · Technology
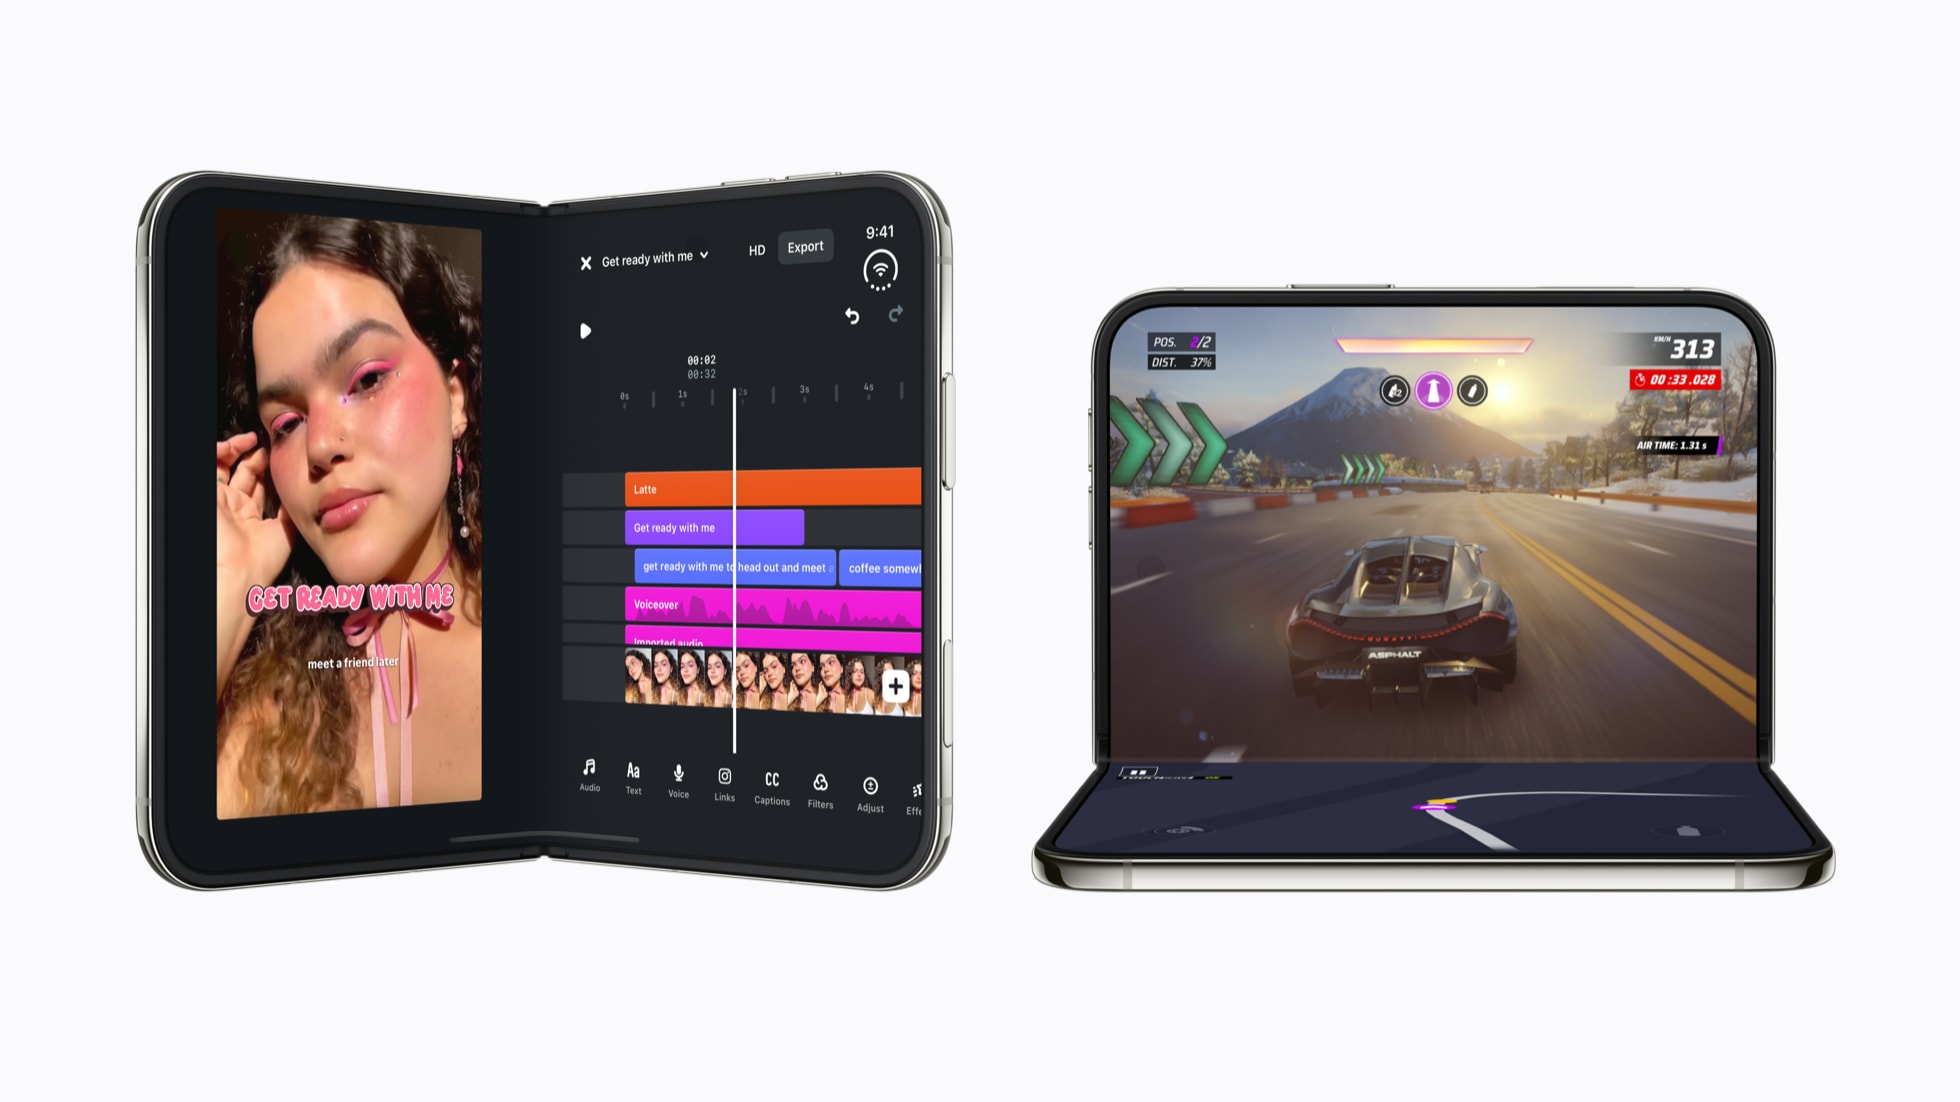
Apple Introduces New Badge for iPhone Duo Apps and Highlights Optimized Offerings
2 outlets
1w
 Technology
Apple's iPhone Duo 2 Set to Feature Under-Display Face ID
2 outlets
1w
 United States
 · Technology
Meta Faces Historic $35 Billion Fine Over Privacy Violations
1 outlet
1w
2 outlets
2 reports
Published Sep 3, 2026
What to know
- Learn how to deploy vLLM NVIDIA Dynamo inference in production with Docker Compose and tuned PagedAttention to eliminate memory fragmentation. How to Deploy vLLM NVIDIA Dynamo Inference for High-Throughput Serving on SitePoint.S1
- NVIDIA Dynamo is an open-source, high-throughput, low-latency inference framework for deploying large-scale generative AI and reasoning models across multi-node, multi-GPU environments. It boosts LLM inference efficiency and reduces time-to-first-token (TTFT)...S2
Timeline · newest first
Related stories
Technology
Technology
Amazon Renames Kindle Unlimited to Kindle Plus, Expands Audiobook Selection
2 outlets
1w
United States
United States · Technology
Apple Introduces New Badge for iPhone Duo Apps and Highlights Optimized Offerings
2 outlets
1w
Technology
Technology
Apple's iPhone Duo 2 Set to Feature Under-Display Face ID
2 outlets
1w
United States
United States · Technology
Meta Faces Historic $35 Billion Fine Over Privacy Violations
1 outlet
1w